In May I wrote in quite some detail about why MCP should be dead. Since then, the protocol has changed more than in the whole year before, and I spent two days at AGNTCon + MCPCon in Amsterdam listening to the people who build it. https://agntconmcpconeu26.sched.com/
Some of my criticism is fixed now. Some is not.
After attending multiple sessions, building a few internal MCP servers and updating others to the new spec, here's what I've taken away:
sessions are gone
The spec with the refreshingly simple name 2026-07-28 was published.
Before, a remote call started with an initialize handshake and a session ID that pinned the client to one server instance. If your MCP adoption grew, scaling meant sticky routing.
The load balancer had to remember which client belonged to which instance, or you needed a shared session store, for example Redis or Valkey, so that every instance could read every session.
With sticky routing, the load is not shared fairly. One instance could get many long sessions while another stayed idle, and a new instance created through autoscaling would only get new sessions. When an instance restarted, crashed or was replaced during a deployment, all of its sessions were gone. The client then had to start again with a new handshake, and an open stream could break in the middle of the work.
A shared session store fixes this, but adds a new component that every request depends on. If the store is slow, every tool call is slow. If it is down, nothing works. It also holds the state of every user in one place, which makes it a valuable target. You see what this entails.
Now every request carries the information needed to handle it, and any instance can answer it. https://blog.modelcontextprotocol.io/posts/2026-07-28/
If an app needs state, one tool can return a handle like cart_id and the model passes it into the next call. https://blog.modelcontextprotocol.io/posts/2026-07-28-release-candidate/ My beloved CLIs have always worked like this: gh pr create prints a number, and the agent uses it in the next command.
In my opinion, this is a big part of why MCP got better. It moved closer to how a CLI works.
what I underrated
The biggest one is security.
CLI + Skill only works if the agent has a shell. For a coding agent that is fine, but a shell together with private data, untrusted content and network access is what Simon Willison calls the lethal trifecta. https://simonwillison.net/2025/Jun/16/the-lethal-trifecta/ He argues that named tools with a schema are much easier to audit than an agent that can run any command it wants. https://simonwillison.net/2026/Jul/31/stateless-mcp/
Chat assistants, tools for non-developers and multi-tenant systems should not give the agent a shell at all. A small, typed set of tools sounds like the right answer, and stateless MCP is now a reasonable way to build it.
I'm however still a bit sceptical about the security part. A remote MCP server is still another party you're sending data to, and schemas don't magically make that server trustworthy. If sensitive context ends up in tool arguments, the server gets it. MCP gives us a much better permission boundary than a shell, but not a trust boundary for free.
WebMCP
WebMCP lets a website register tools on document.modelContext, so a browser agent can call them directly. https://developer.chrome.com/docs/ai/webmcp/imperative-api
if (document.modelContext) {
  await document.modelContext.registerTool({
    name: "book_table",
    description: "Book a table for a date, time and number of guests.",
    inputSchema: { /* JSON Schema */ },
    annotations: { consequentialHint: true },
    execute: async (args) => bookTable(args),
  });
}
Today a browser agent works in a loop: screenshot, reasoning, click, next screenshot. With WebMCP the site offers book_table with a schema, and the agent makes one call. The consequentialHint annotation marks actions like payments, so the browser can ask the user to confirm first.
Chrome describes it as MCP-inspired, and the tools only exist while the tab is open. https://developer.chrome.com/docs/ai/webmcp/compare-mcp It is an origin trial from Chrome 149, and the API has already changed: navigator.modelContext is deprecated in favour of document.modelContext. https://docs.copilotkit.ai/webmcp, https://dev.to/jangwook_kim_e31e7291ad98/webmcps-origin-trial-providecontext-is-already-gone-54j8
[!IMPORTANT] I've implemented it on Veganify.app and it works well, so feel free to play around with it.
To try it out today, you need to enable chrome://flags/#enable-webmcp-testing in Chrome. You'll then be able to see all registered WebMCP tools in the DevTools console, and call them from the console as well:
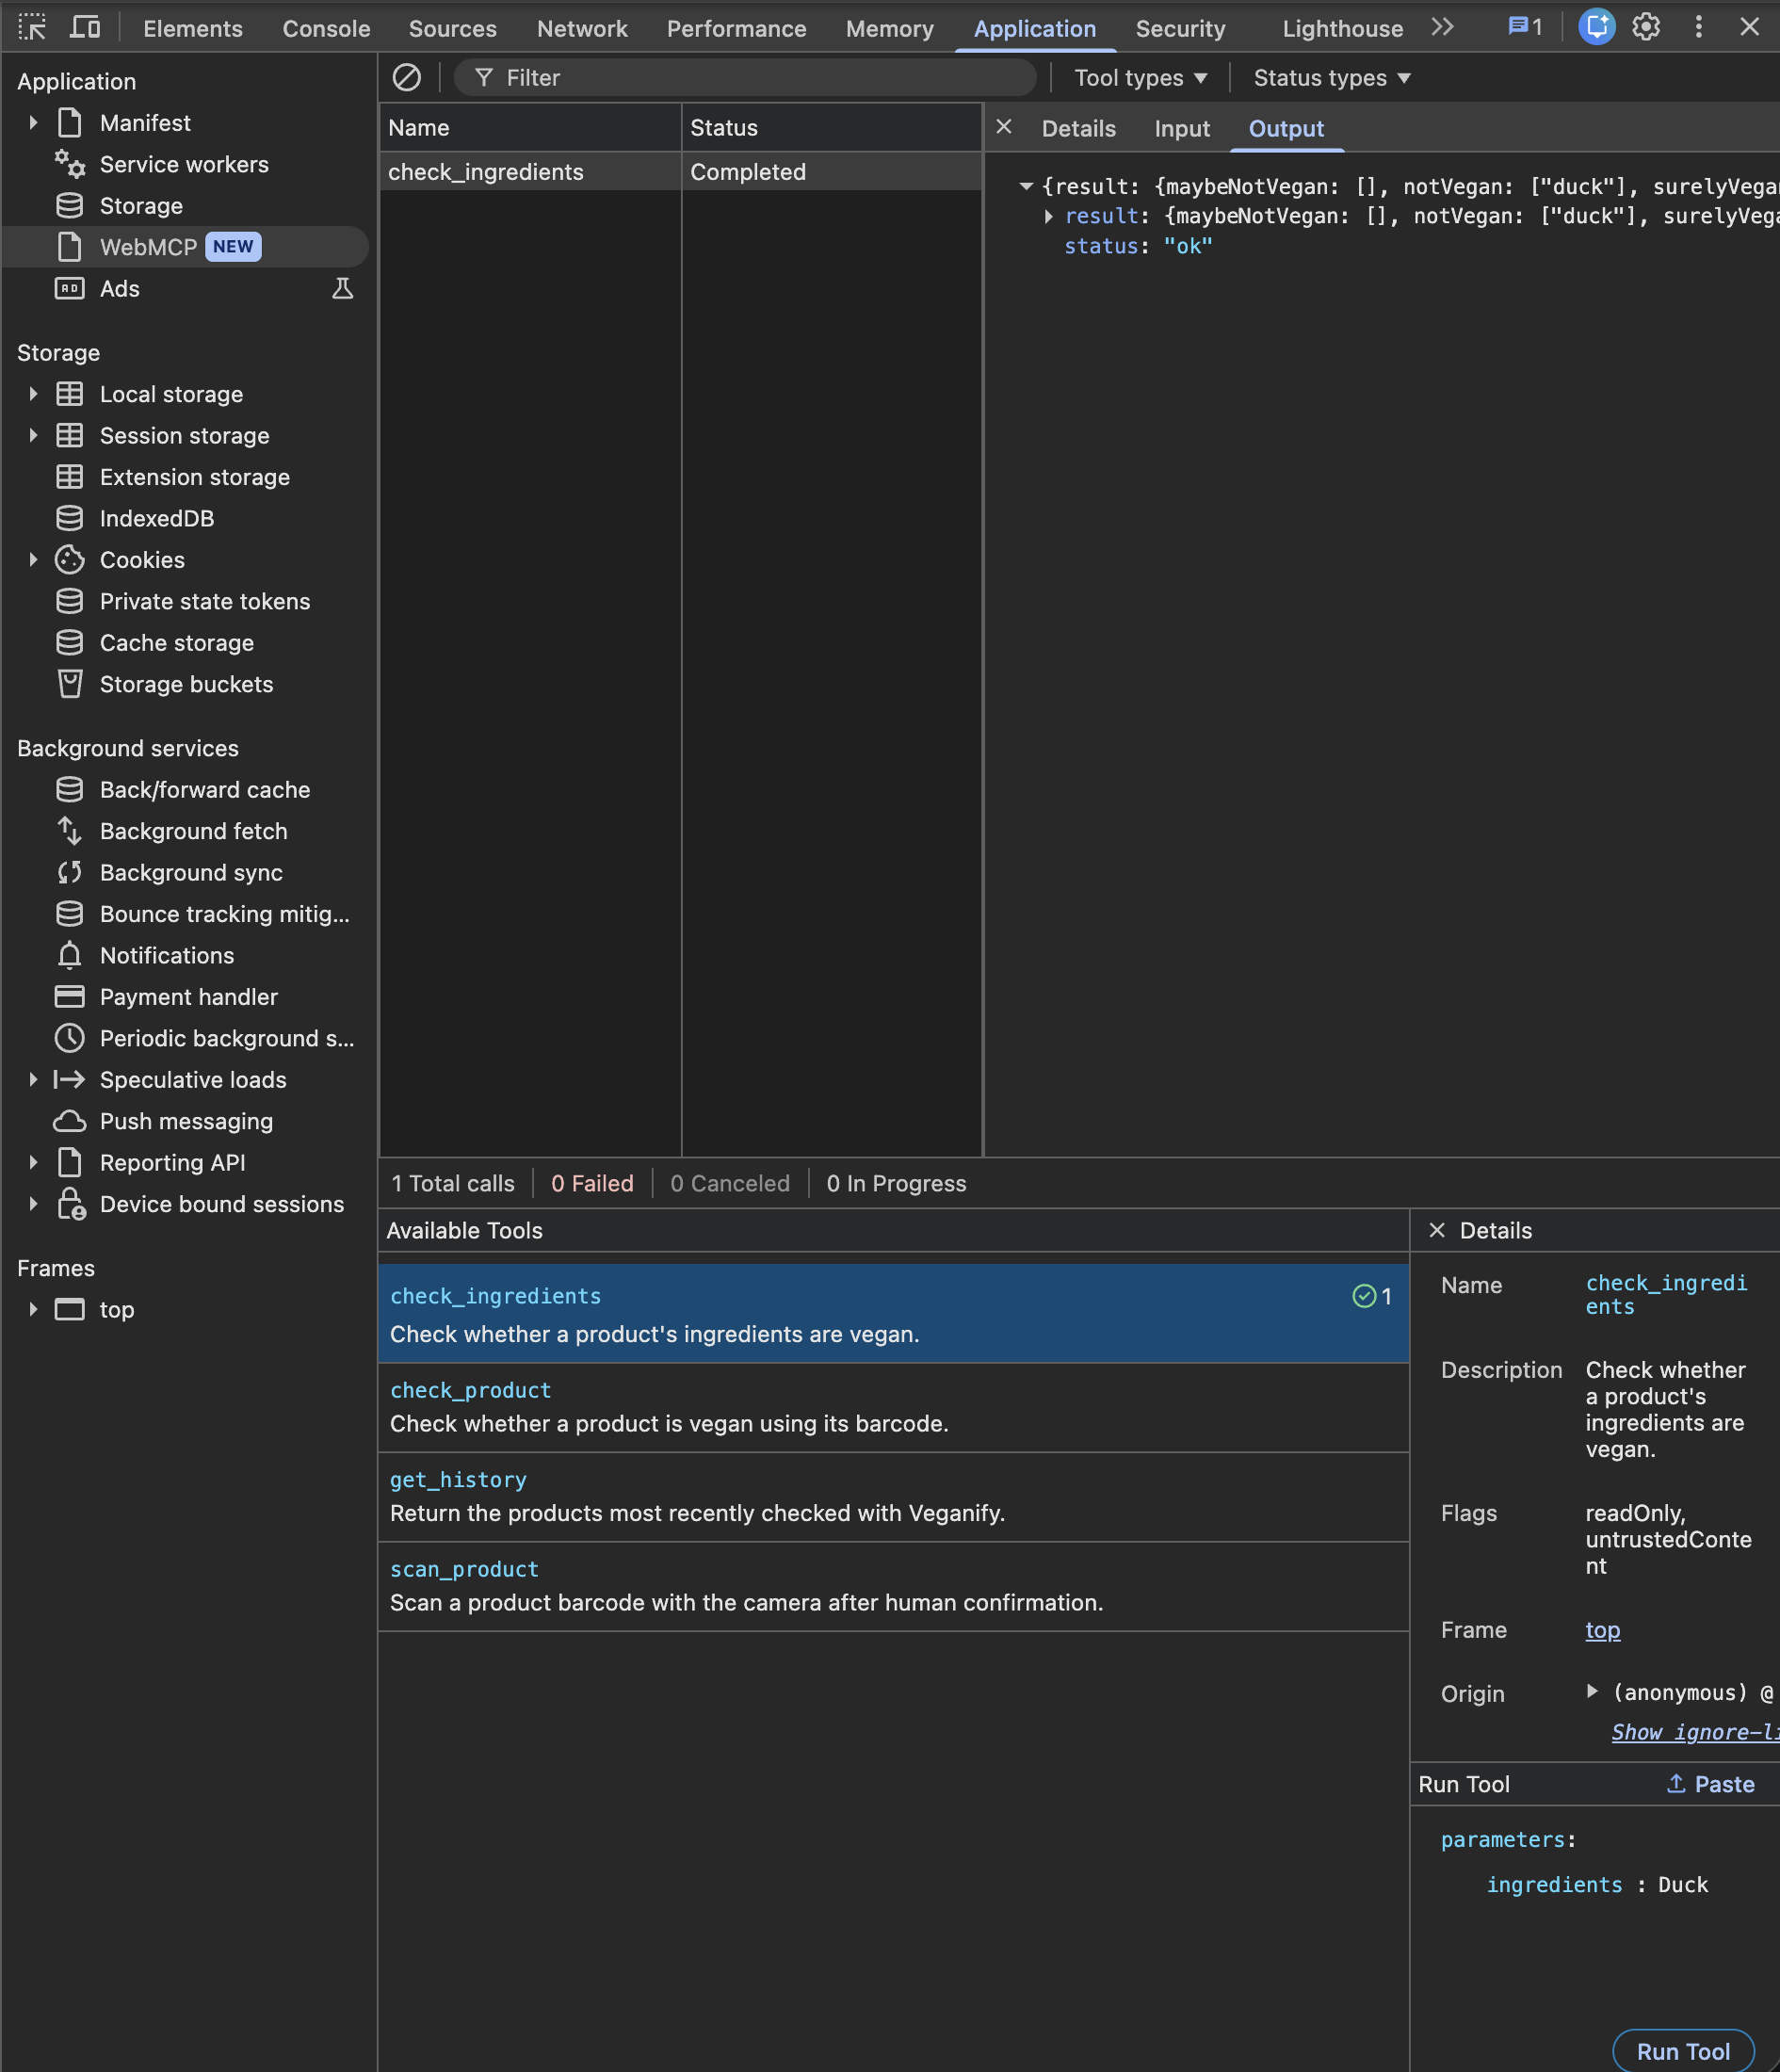
People are using agents more and more, and while this might be behind a feature flag and pretty niche today, with tools like Meta's Muse or OpenAI's Dots, as well as the more nerdy ones like Hermes or OpenClaw, this will become more important.
As someone who started in frontend engineering, my heart is bleeding a bit, but I think this is a good step forward for the web.
what I still don't like
There are effectively two generations of MCP in use now. The change is breaking, and some clients are stuck on older SDKs or on infrastructure that expects the old handshake. https://inside.java/2026/08/12/java-mcp-migration/ For a while, "supports MCP" can mean either revision, and it will probably take much longer until the ecosystem is fully on the new one.
Extensions fragment the ecosystem. After Skills went final, a probe of 572 reachable public MCP servers found two that support it. https://dev.to/piekwerk/skills-over-mcp-is-final-what-3-methods-and-per-file-digests-change-for-your-agents-25jk OpenAI supports the extension, but uses it at build time to package plugins rather than serving skills live. https://www.arcade.dev/blog/skills-over-mcp-explained So what an extension does in practice depends on the host you use.
And if one team exposes one API to one agent it controls, MCP is still an extra layer on top of what is now plain HTTP.
where I am now
For coding agents I still use CLIs first. The shell is already there, and the agent can pipe output through jq or head before it reaches the context. An MCP result arrives the way the server author wrote it. When Simon wanted to explore stateless MCP servers, he built a CLI for it, mcp-explorer. https://simonwillison.net/2026/Jul/31/stateless-mcp/
For agents that should not have a shell, and for services that many different hosts connect to, I would now pick stateless MCP.
In May I looked at MCP from the model's side, meaning tokens and parsing. From that side, the CLI still wins.
From the side of the person who decides what an agent is allowed to access, MCP looks a lot better than I said back then.